Apriori
AI personas walk through a product and predict who drops off, and why.
paused
Product testing before you have any users. You describe the audience instead of recruiting it, put a design in front of them, and watch where they get confused. Much cheaper than shipping and finding out.
Synthetic Indian personas walk an onboarding flow screen by screen, a model looking at each screen as that person, and the output says who dropped off and why. It went through a few shapes in early 2026. The April one was built on one line: we don't report which variant won, we build the variant that should exist. In June, live URL testing and a click heatmap shipped, with personas driving a real site in a headless browser.
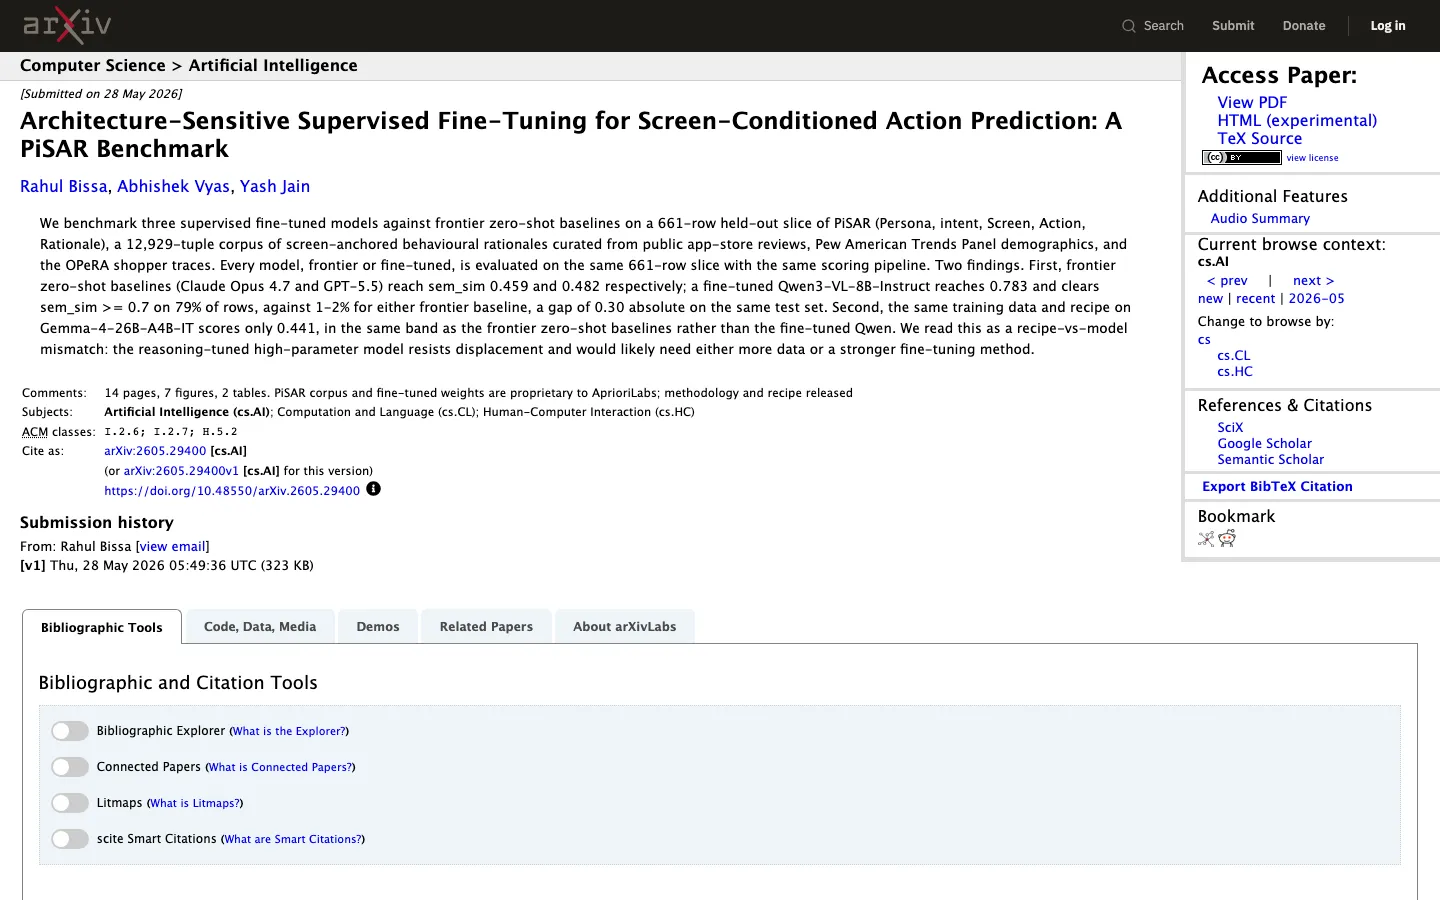
The part I'd show anyone is the paper. Rahul Bissa, Yash Jain and I benchmarked fine-tuned models on PiSAR, a corpus of screen-level behaviour. A fine-tuned Qwen3-VL-8B reached 0.783; Claude Opus 4.7 and GPT-5.5, zero-shot, reached 0.459 and 0.482.
One rule I kept: less data with verified provenance is strictly better than more data with synthetic content.
Link
- paper The PiSAR paper on arXiv